Technology
Microsoft Tells SEMICON Taiwan to Measure AI Infrastructure by Useful Yield
Microsoft says the next phase of AI infrastructure should be judged by tokens per dollar and watt, throughput and latency rather than raw capacity. The argument places cross-layer engineering and operating efficiency at the center of the data-center race.
By Michael G ·
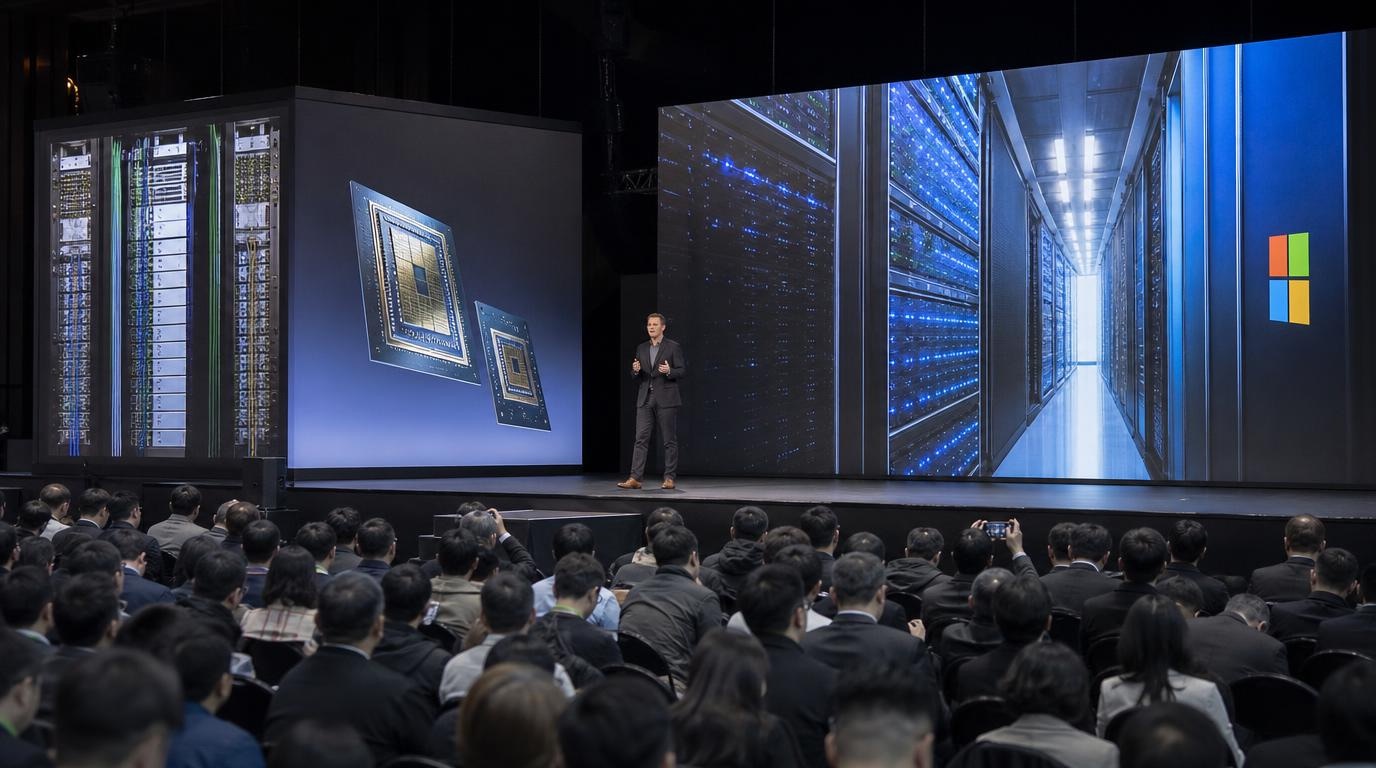
Microsoft used the opening of SEMICON Taiwan 2026 to argue that the AI infrastructure race is entering a less forgiving phase. Rani Borkar, president of Azure Hardware Systems and Infrastructure, said the industry should judge progress by useful yield: how efficiently silicon, memory, networking and power become usable intelligence. The proposed measures include tokens per dollar and per watt, throughput and latency. The message to chipmakers was simple. Capacity still matters, but capacity that cannot be converted into dependable output is an expensive inventory problem.
The framing arrives after years in which spending and accelerator counts served as shorthand for AI leadership. Those numbers remain easy to compare. Useful output is harder because workloads differ, software changes and a token generated for a customer-support reply is not equivalent to one produced during a long scientific agent run. Microsoft is nevertheless pointing at the right engineering constraint: the system matters more than its most marketable component.
A powerful accelerator can wait idle for memory, networking or power. A densely packed rack can deliver poor economics if cooling limits sustained utilization. A model can produce more tokens while wasting them on retries or low-value reasoning. Useful yield forces operators to examine the complete path from grid connection to accepted application result. It also gives customers a more demanding question than which chip sits inside the building.
Cross-Layer Design Becomes the Main Engineering Lever
Microsoft says efficiency gains now require co-design across silicon, memory, networking, power, cooling, compilers, models and fleet operations. That approach is visible in Azure Maia, where accelerator behavior is connected to memory management and a custom scale-up network. It is also visible in Azure Cobalt, where finer-grained power controls are programmed into the CPU so more servers can operate within the same megawatt envelope.
Cross-layer optimization is not new to computing, but AI makes the penalties larger. Training and inference distribute work across many devices, and small inefficiencies compound across a fleet. If one layer cannot keep pace, expensive accelerators sit underused. The fastest improvement may come from changing model placement, transport or scheduling rather than manufacturing a faster chip. That is why cloud operators increasingly design hardware and software together.
The strategy also concentrates power. A company that controls the model, compiler, networking stack, accelerator and cloud scheduler can optimize globally, but customers become more dependent on its implementation. Open interfaces and transparent measurements are needed if useful yield is to become more than a vendor-specific score. Buyers should be able to compare the cost and energy of completing a workload across clouds without adopting each provider's preferred definition.
Memory is a particularly important constraint. Large models move enormous volumes of parameters and intermediate data, and accelerator performance is wasted when memory bandwidth cannot feed it. Microsoft argues that optimization can extract more intelligence from each byte through model design, placement and compiler decisions. The result may be less visible than a new processor, but it can determine whether a service is affordable at scale.
Tokens per Watt Still Need a Quality Threshold
A productivity metric can create perverse incentives if it counts output without quality. A model that generates twice as many tokens is not more useful when those tokens require correction. The numerator should reflect accepted work: an answer that passes evaluation, a code change that clears tests or an agent task completed within policy. Otherwise the industry will optimize visible throughput while hiding retries, hallucinations and human review.
Latency has the same ambiguity. Fast first-token response improves a conversation, but an enterprise workflow may care more about time to verified completion. An agent that responds immediately and then loops through tools for ten minutes can feel fast while delivering slowly. Infrastructure measurement should distinguish interactive responsiveness from end-to-end task time, including queues and external dependencies.
The financial implications extend through the semiconductor supply chain. If customers demand useful yield, accelerator vendors will compete on software maturity, networking and sustained fleet performance rather than peak specifications. Memory suppliers, cooling companies and power-management specialists gain strategic weight because their products release capacity that is otherwise stranded. The AI trade broadens from a GPU story into a systems story.
Taiwan is the right place for that argument. Its foundries and suppliers sit inside nearly every advanced AI system, while power, land and geopolitical risk constrain expansion. Useful yield offers a way to increase output without assuming infinite new capacity. It does not remove the need for more facilities. It changes the return expected from each wafer, rack and megawatt.
Sustainability claims should remain tied to absolute consumption. Improving tokens per watt can lower the energy required for one task while total demand rises much faster. Efficiency can make AI cheaper and therefore more widely used, offsetting part of the saving. Operators should report both intensity and total electricity, water and emissions. A better ratio does not automatically mean a smaller footprint.
Cloud buyers will need workload-specific disclosure to use the metric. Training, batch inference, interactive chat and long-running agents place different pressure on a system. An average fleet number can conceal poor performance for the application a customer actually runs. Providers could publish ranges by workload, region and accelerator generation, then let customers measure their own accepted-output rate. Useful yield becomes meaningful only when the unit of usefulness is visible.
Reliability belongs in the denominator as well. A densely optimized cluster that fails often may post attractive peak throughput while producing less usable work over a month. Scheduled maintenance, retry traffic and unavailable capacity consume capital even when they disappear from a benchmark window. Sustained yield should account for real availability and the cost of keeping enough spare capacity to meet service commitments.
The approach may change how capital is allocated inside Microsoft. Teams proposing a new accelerator or data-center design can be evaluated against the output it unlocks rather than the hardware it adds. That encourages investment in software, cooling and networking improvements that are less visible but may deliver faster returns. It can also expose stranded capacity, a sensitive issue after the industry committed hundreds of billions of dollars to AI buildouts.
For model developers, infrastructure efficiency becomes a design constraint rather than a cloud-provider concern. Architecture, quantization, context handling and speculative decoding can change the amount of useful work extracted from the same machines. A model that scores slightly lower but finishes customer tasks with fewer retries may create more value. The best system is not always the one with the largest parameter count or the highest isolated benchmark.
Governments may eventually use useful-yield measures when reviewing data-center incentives and grid allocations. If projects request scarce power, officials will want evidence of economic output and efficiency. That creates a risk of politicized or easily gamed metrics. Common reporting standards, independent audits and clear environmental accounting would make comparisons more credible before useful yield influences permits, subsidies or infrastructure planning.
Useful yield is ultimately an accountability framework. It asks infrastructure companies to show what society receives for historic capital and energy commitments. The strongest version will connect physical inputs to trustworthy application outcomes and expose the costs that raw token counts ignore. The weakest version will become another benchmark optimized for a keynote. Microsoft has named the right destination; the next task is publishing measurements that customers can independently use.
Topics: Microsoft, SEMICON Taiwan, AI infrastructure, semiconductors, data centers