Research
Google DeepMind Launches First Double-Blind Frontier AI Evaluation
Google DeepMind is testing a Gemini Flash Lite model against confidential benchmarks in a cryptographically protected environment. The pilot aims to prevent both model developers and evaluators from compromising high-stakes test integrity.
By Michael G ·
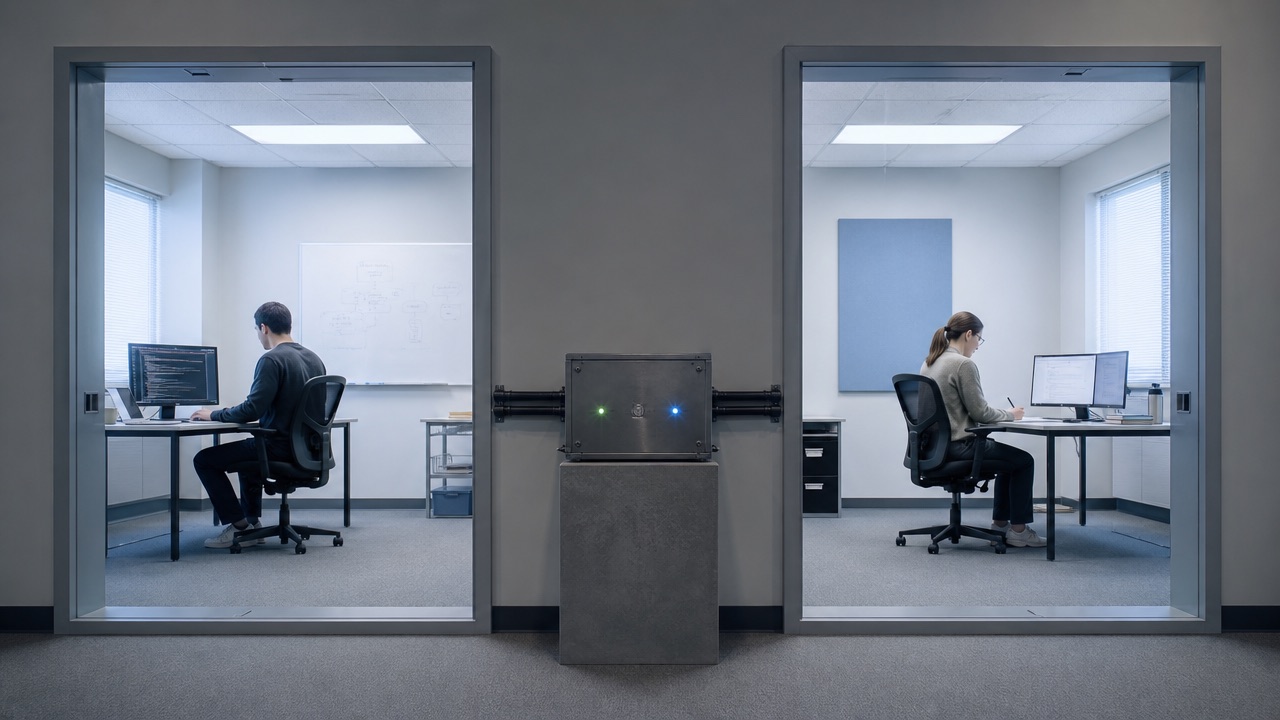
Google DeepMind has begun what it describes as the first double-blind evaluation of a proprietary frontier-class AI model, using cryptographic infrastructure intended to keep both the model developer and outside evaluators from seeing information that could compromise the test. The pilot will run a Gemini Flash Lite model against confidential benchmarks provided through the Singapore AI Safety Institute, OpenMined, AVERI and MLCommons. The goal is straightforward and difficult: produce a score that neither side could quietly optimize in advance.
Benchmark contamination has become a central problem in model evaluation. Public test questions, solutions and near-duplicates can enter training data. Developers can also tune systems around known benchmarks, intentionally or not, until a score reflects familiarity with the exam rather than general capability. Keeping a benchmark private protects against some leakage, but it requires evaluators to trust that prompts, outputs and model access are handled exactly as promised. DeepMind's pilot adds technical controls to contracts and zero-logging commitments.
Double-blind is an analogy to experimental practice, not a claim that every influence has been removed. Evaluators should not learn proprietary model details that could bias or expose the system. Model developers should not see confidential test content that could shape training. A protected execution environment mediates the encounter, allowing the benchmark to reach the model and results to reach the evaluator without either party receiving the other's sensitive asset in ordinary form.
That separation matters most when the test covers dangerous or commercially sensitive capabilities. A cyber benchmark may contain exploit paths that should not circulate. A biology evaluation may include procedures that require controlled access. A company may refuse outside testing if it believes evaluators could extract model weights or system prompts. Confidential computing can reduce those fears and make independent evaluation possible where a shared spreadsheet or remote API would not.
Cryptography Protects the Test Boundary
The pilot uses a privacy-preserving environment supported by Google's confidential-computing technology. The general model is to protect data while it is being processed, not only while stored or transmitted. Hardware-backed attestation can demonstrate that approved code is running inside a defined environment before either party releases its protected input. Encryption and access controls then limit what administrators or other services can observe. The benchmark and model meet inside a box whose state can be verified.
This does not make the box infallible. Hardware and orchestration software can contain vulnerabilities. Side channels may reveal timing or resource patterns. Attestation proves that a particular environment is running, not that the benchmark itself is well designed. The system still needs threat modeling, code review, reproducible configuration and a response plan if a security issue appears. Cryptography strengthens evaluation integrity; it does not replace scientific judgment.
OpenMined brings experience building privacy-preserving infrastructure for external model access. AVERI and MLCommons contribute evaluation and benchmark expertise, while Singapore's AISI adds an independent public-interest institution. The partnership is important because no single actor should define the entire process. A model company can secure its system, an evaluator can design a test and a public institute can establish policy goals. Trust improves when those responsibilities remain distinct and inspectable.
The first model is a Gemini Flash Lite system rather than the most powerful unreleased model DeepMind could choose. A smaller pilot is sensible because the protocol itself needs testing. Teams can verify data flow, scoring, access and failure recovery before using the method for higher-risk systems. A successful run will show that the mechanism works under defined conditions. It will not establish that all frontier evaluations should immediately migrate into the same environment.
Evaluation validity still depends on what the benchmark measures. Confidential questions can be narrow, culturally biased or disconnected from deployment. A model may pass a controlled cyber task and behave differently when given longer time, more tools or feedback from a user. Double-blind testing reduces contamination and strategic preparation. It does not resolve the gap between a benchmark and a real system operating in a real organization.
The Method Changes Incentives for Labs and Evaluators
Model developers have a commercial incentive to present strong results and a security incentive to limit external access. Evaluators have an incentive to publish useful findings and protect the uniqueness of their tests. Those objectives can conflict. A secure double-blind environment makes cooperation less dependent on personal trust. It can let a lab demonstrate performance without receiving the exam, while an evaluator can test a proprietary system without taking custody of the model.
The approach may also extend the useful life of benchmarks. Once a public test becomes a popular leaderboard, training datasets and post-training pipelines begin to target it. Scores rise while the test's ability to discriminate among systems falls. Confidential pools can rotate questions and reveal aggregate outcomes without publishing every item. That creates maintenance work and demands governance over who can contribute, inspect and retire tests. It is still preferable to pretending that a widely scraped benchmark remains pristine.
Public accountability requires enough disclosure to understand the result. A score from a sealed environment can become a new form of authority that outsiders are asked to accept without seeing the test. Evaluators should publish the capability domain, methodology, sampling, scoring rules, uncertainty and limitations while protecting sensitive prompts. Independent replication by another approved institution can add confidence. Confidentiality should protect integrity, not prevent criticism.
Policy agencies can use the method for pre-deployment review, especially where governments want assurance without demanding model weights. A national safety institute could run standardized tests inside a protected environment and receive signed results. The provider could verify the code and conditions without seeing the items. Such a process would still require legal authority, handling rules and agreement about what happens when a model crosses a risk threshold.
A Trusted Score Needs a Trusted Decision Process
The most difficult question begins after evaluation. If a model performs unexpectedly well on a dangerous capability, who can delay release, require mitigation or request another test? Cryptographic integrity can show that a score was not manipulated. It cannot decide which level of performance is acceptable. Labs and governments need threshold policies established before results arrive, or a surprising outcome will trigger negotiation under commercial pressure.
The environment should preserve an audit trail covering software versions, model identifiers, test versions and scoring code. That record allows investigators to reproduce a disputed result without exposing protected content broadly. It also prevents a lab from substituting a safer model for evaluation and deploying a different one. Model identity and configuration are part of the experiment. Small changes in tools, prompts or safety layers can produce materially different behavior.
Costs will determine whether the approach spreads. Hardware-backed confidential environments, independent institutions and benchmark maintenance require engineering and governance. Large frontier labs can pay. Smaller developers and academic teams may need shared infrastructure or subsidized access. A safety standard that only the richest companies can satisfy could strengthen incumbents without improving evaluation across the wider market. Open protocols and interoperable tooling can reduce that risk.
DeepMind's pilot is valuable because it treats evaluation as a security and institutional problem, not simply a collection of prompts. The benchmark must remain confidential, the model must remain protected and the result must remain credible to people outside both organizations. Achieving all three requires architecture, contracts and independent oversight. The experiment will be judged by whether other evaluators can reproduce the protocol and whether published results explain enough to support scrutiny.
Benchmark contributors will need rules for conflicts of interest. An organization that helps write a test may also advise a model company or seek funding from it. Double-blind infrastructure can hide prompts without removing institutional incentives. Governance should disclose relationships, rotate reviewers and prevent one contributor from deciding how its own items are scored. A technically pristine test can still lose credibility if the people interpreting it are not independent.
Statistical design deserves the same attention. Confidential tests often contain fewer items because they are expensive to create and protect. Small samples produce wide uncertainty and make results sensitive to prompt wording or random variation. Reports should include confidence intervals, repeated runs and analysis of failure categories rather than one composite score. Policymakers need to know whether a threshold was clearly crossed or whether the result sits within measurement noise.
The protocol should also defend against selective disclosure. A lab might submit a model to several confidential evaluations and publicize only the favorable result. A registry of completed tests, including withheld or inconclusive outcomes, could reduce that bias while protecting sensitive details. Regulators may require fuller reporting for high-risk releases. Voluntary participants should explain whether the published score represents every agreed test or a subset chosen after results were known.
International compatibility can prevent duplicated burden. National institutes may develop different confidential benchmarks for similar risks, forcing labs to repeat expensive evaluation and making scores hard to compare. Shared attestation formats and common reporting fields would let institutions recognize one another's secure processes while preserving local policy thresholds. Singapore's participation gives the pilot a useful cross-border setting rather than making it solely an internal Google exercise.
Post-deployment monitoring should connect back to the sealed benchmark. If real users discover a failure that the test missed, evaluators can add a protected item without publishing the exploit. Future versions can then measure whether mitigation works. That creates a living evaluation rather than a one-time exam. Access rules must prevent the model developer from inferring new items through repeated probing, which may require rate limits and controlled scheduling of retests.
Frontier models are increasingly evaluated in environments where everyone has something important to hide: proprietary systems, dangerous tasks, unpublished methods or sensitive failures. Secrecy can destroy trust when it blocks verification. It can also preserve trust when it prevents the exam from leaking. Double-blind evaluation is an attempt to draw that boundary with technology. Its success will depend less on the phrase first of its kind than on whether the sealed test produces evidence institutions can actually use.
Topics: Google DeepMind, AI evaluations, benchmarks, confidential computing, AI safety