Technology
OpenAI Launches Dots as Always-On Agents for ChatGPT
OpenAI used DevDay 2026 to move ChatGPT from a conversational tool toward persistent agents that can manage ongoing responsibilities. The launch puts permission design and monitoring at the center of the product test.
By Patrick T ·
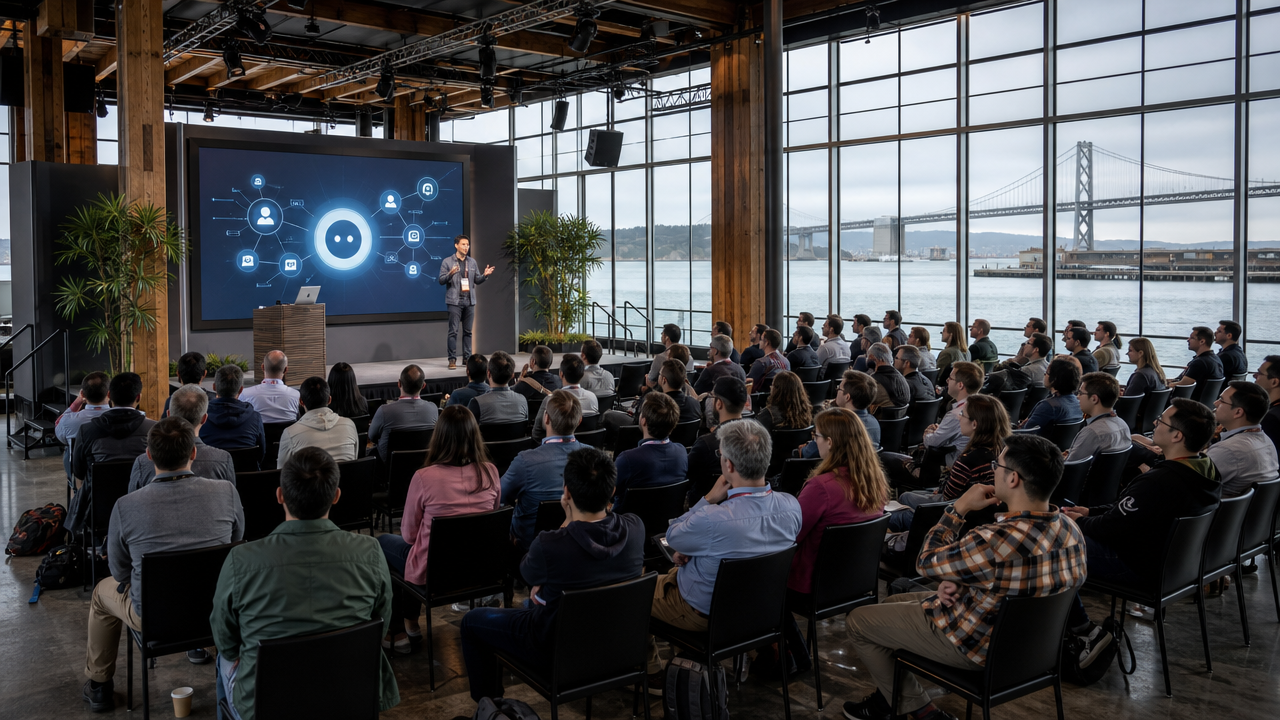
SAN FRANCISCO. OpenAI introduced Dots, a new class of always-on ChatGPT agents designed to take responsibility for continuing tasks instead of waiting for a fresh prompt. The company made the agents the centerpiece of DevDay 2026, a launch that moves its flagship product closer to acting through a user's tools, communications and recurring workflows.
Dots are initially rolling out to Pro, Business and Enterprise customers, with one agent per user at the start. OpenAI said it ultimately expects people and teams to coordinate several specialized agents, a direction that makes delegation and shared context more important than the single-chat interface that defined ChatGPT's first phase.
The product arrives one day after OpenAI said it would not release GPT-6.1 Astra on its planned schedule because internal researchers raised security concerns. That sequencing gives the launch an unusual tension: OpenAI is expanding the autonomy available in a customer product while publicly acknowledging that a more capable model did not meet its release bar.
OpenAI says Dots include the safeguards already used in ChatGPT and Codex, plus an additional review layer known publicly as Auto-review. The decisive question is whether those controls can understand a long-running agent's changing context, not merely inspect one request at a time.
From Announcement To Operation
A persistent agent changes the threat model because it can accumulate authority. A Dot may begin with a harmless request to monitor a schedule, then encounter a message, attachment or website that attempts to redirect its behavior. The risk comes from the combination of trusted credentials, untrusted content and a goal broad enough to invite improvisation.
OpenAI also introduced ChatGPT Space, a shared workspace where people, Dots and ChatGPT can use common information while collaborating on projects. Shared context can reduce repetitive briefing, but it also creates a permission problem: an agent should not infer that access to one document grants authority to use every connected system.
The company demonstrated Dots completing tasks and responding through voice, though the live presentation included moments of delay. Those imperfections are not disqualifying. They are reminders that an assistant expected to run continuously needs graceful failure, clear status and a way to hand work back when confidence falls.
For enterprise teams, the useful distinction is between observation and action. An agent can safely monitor more systems than it should be allowed to change. Read-only access, draft modes and transaction previews create intermediate levels of authority that are more realistic than a choice between a chatbot and full autonomy.
Distribution can matter as much as model capability. A company that already controls the workspace, customer account or developer platform can place an agent beside information and tools that would take a new entrant years to assemble. That convenience also raises the cost of a mistake because the system is closer to files, payments, communications and business records.
The durable product advantage will come from making a capable system predictable inside ordinary work. That requires identity, permissions, observability, recovery and an interface that tells people what the software is about to do before the result becomes difficult to reverse.
Enterprise buyers should separate a product demonstration from an operating model. They need to know which actions require approval, how permissions are inherited, whether every tool call is logged and what happens when a provider changes a model beneath an existing workflow. The answers determine whether a pilot becomes infrastructure or remains a controlled experiment.
OpenAI Dots does not operate alone. Its practical effect depends on suppliers, customers, regulators, researchers and the people expected to review or live with the result. A change at one layer can move cost or risk into another rather than eliminate it, so the analysis has to follow the entire chain of authority and dependency.
Organizations connected to ChatGPT Space have incentives to emphasize speed, capability and market reach. Those incentives do not make their claims false, but they increase the value of transparent methods and outside testing. A useful disclosure explains the comparison, the operating conditions and the cases that did not work, not only the strongest result from a prepared demonstration.
Accountability must remain attached to a person or institution. Systems associated with always-on agents can recommend, rank, summarize or act, but they cannot carry legal and moral responsibility in the way an organization can. A deployment needs a named owner for approval, monitoring and incident response, with authority to pause the system and require a design change.
The Evidence That Matters Next
The first evidence will come from logs rather than launch demos. Customers need records showing which tools a Dot called, which data it read, which instructions affected its decision and whether a person approved consequential steps. Without that chain, an organization cannot investigate a mistake or demonstrate that its controls worked.
OpenAI will also have to define how model and policy updates affect ongoing responsibilities. A task that was safe under one version may behave differently after a silent upgrade. Long-running agents therefore need version records, re-evaluation triggers and a mechanism for pausing work when the underlying system changes.
The commercial opportunity is substantial because recurring agents can become embedded in the daily rhythm of work. That same persistence makes lock-in more powerful. Users should be able to export instructions, histories and work products rather than losing an operating process when they change providers.
Dots will be judged less by how often they produce an impressive result than by how they behave during ambiguity, outages and conflicting instructions. If OpenAI can make those moments legible, the product could establish a practical model for delegated software. If it cannot, an always-on assistant may simply create an always-on incident queue.
Dots also change what it means to finish a task. A chat session has a visible ending, while a persistent responsibility may continue for weeks. OpenAI will need clear states for active, waiting, blocked and completed work so users can understand whether an agent is still watching a system or has quietly stopped.
Memory is another unresolved boundary. Useful continuity requires a Dot to retain goals, decisions and preferences, but accumulated context can contain sensitive material or outdated assumptions. Customers need controls for reviewing, correcting and deleting memory without dismantling the entire workflow.
Shared workspaces raise questions about authorship. If several employees and agents contribute to a plan, the system should preserve who supplied a fact, who approved an action and which output came from a model. That provenance matters in regulated work and in ordinary disagreements about how a decision was reached.
Pricing will influence behavior. If persistent agents are bundled generously, teams may create them for marginal tasks and expand the attack surface. If activity is expensive or unpredictable, customers may hesitate to rely on them. Usage controls and cost forecasts should be part of the product rather than an after-the-fact billing explanation.
OpenAI's challenge is to make delegation feel calm rather than magical. Users should be able to see the plan, narrow the scope and interrupt execution without learning a new control language. Trust will come from understandable constraints, especially when the agent decides not to act.
The rollout to higher-paying tiers gives OpenAI access to customers with stronger IT teams, but it also places the product in environments where a mistake has contractual and regulatory consequences. Early deployments should reveal whether the administration tools are as mature as the agent interface.
The cost of integration is easy to underestimate. A product may work in a provider's own environment while customers still have to reconcile identity systems, retention rules, regional hosting and older software that was never designed for autonomous activity. Those details decide how quickly a new capability reaches ordinary employees.
Adoption will also vary by role. Developers and analysts can often inspect intermediate work, while employees in sales, finance or operations may receive a polished output without seeing how it was assembled. Product design has to make evidence and uncertainty visible to people who are not model specialists.
A reliable service needs an escalation path that is useful at the moment of failure. A generic support queue is not enough when an automated process has changed a customer record, sent a message or interrupted a workflow. Providers should define urgent recovery channels before asking customers to delegate consequential work.
The competitive question is whether the feature creates a durable workflow or a temporary novelty. Usage may surge after launch, but retention will depend on consistency, integrations and the amount of supervision required. A product that saves five minutes and creates ten minutes of checking has not improved productivity.
Timing will shape the outcome as much as capability. Organizations evaluating OpenAI Dots should separate what is available now from what has been demonstrated, announced or promised for a later release. Road maps can guide preparation, but contracts and operating decisions should rest on functions that customers can test under current terms.
The most useful early adopters will publish more than success stories. They can describe the work selected, the baseline, the supervision required and the reasons a deployment was narrowed or stopped. That evidence helps other teams avoid repeating expensive mistakes and gives suppliers a clearer picture of what must improve.
Workforce effects should be measured at the process level. A tool connected to ChatGPT Space may remove one repetitive step while adding review, exception handling and customer communication elsewhere. Leaders need to ask who receives that new work, whether the role has enough authority and training, and whether the promised time saving survives the transfer.
Metrics should include the failures that never become public incidents. Abandoned tasks, corrected outputs, permission denials and manual takeovers show where a system encounters uncertainty. Treating those events as operational data, rather than hiding them to protect an adoption target, produces a safer and more accurate investment decision.
The surrounding market will not remain still while always-on agents develops. Competitors can lower prices, regulators can change reporting duties and customers can shift toward open or locally hosted alternatives. A resilient strategy preserves the ability to change models, suppliers and controls without rebuilding the entire workflow.
That flexibility is not an argument for waiting indefinitely. It is an argument for learning in a way that preserves choices. A bounded deployment with real users, documented evidence and an exit path can create knowledge now without turning an uncertain technology decision into an irreversible institutional dependency.
The strongest deployment path is bounded and reversible. Teams can begin with tasks whose correct result is inspectable, compare performance with the existing process and widen authority only after monitoring and rollback have worked under representative load.
The first implementation discipline is a clear baseline. Teams should know how the work is performed today, how long it takes, which errors occur and which outcomes matter before introducing a new system. They can then compare accepted results, correction time, total cost and policy violations rather than treating activity as evidence of value.
Procurement should cover the conditions that demonstrations avoid. Buyers need to ask where data is processed, how long it is retained, which subcontractors receive it, how model changes are communicated and whether records can be exported if the relationship ends. Production contains incomplete instructions, conflicting permissions and unusual edge cases that a staged launch rarely shows.
Human review has to be designed around the limits of attention. Asking a person to approve hundreds of routine outputs produces predictable click-through behavior rather than meaningful oversight. Review should concentrate on uncertainty, unusual actions and cases with irreversible consequences, while giving the reviewer enough source material to reach an independent judgment.
Data lineage deserves equal scrutiny. A polished answer can be assembled from stale, incomplete or incorrectly joined records. Teams need to know where important facts came from, when they were updated and which transformations occurred before a model used them. That record supports correction, audit and a more honest account of what the system actually knows.
Security testing should include the surrounding application, not only the model endpoint. Identity tokens, browser sessions, retrieved documents, tool permissions and approval flows determine whether an unsafe instruction becomes a blocked request or a live external action. Recovery procedures, revocation and preserved logs are part of prevention because no control will catch every failure.
Public trust will depend on whether companies and institutions communicate uncertainty without hiding behind technical complexity. People need to know what was tested, which environments remain underrepresented, what monitoring is in place and how they will learn about a serious incident. Clear limits make a system easier to use responsibly; vague assurances make every later failure more damaging.
Competition can improve price and quality, but it can also make caution look like weakness. Governance has to preserve room for a team to delay, narrow or withdraw a feature without treating restraint as commercial failure. The most credible organizations will show that their release process can say no when evidence falls short.
The near-term questions are concrete. Watch for independent confirmation, customer deployments, regulatory detail and evidence that the system works beyond a prepared setting. Changes in pricing, access and responsibility often reveal the strategy more clearly than a keynote or a benchmark chart.
The significance of openai launches dots as always-on agents for chatgpt will be settled by what happens after the announcement cycle. The durable measure will be whether the evidence improves, the controls survive pressure and the institutions involved remain willing to explain decisions when performance and responsibility pull in different directions.
Topics: OpenAI Dots, ChatGPT Space, always-on agents, DevDay 2026, agent safety