Policy
White House and AI Companies Sign Voluntary Super-Intelligence Accord
The Trump administration and leaders from OpenAI, Anthropic, Google, Meta, Nvidia and xAI agreed to voluntary reviews and an oversight committee. The accord tests whether industry self-policing can carry public authority without enforceable rules.
By Michael C ·
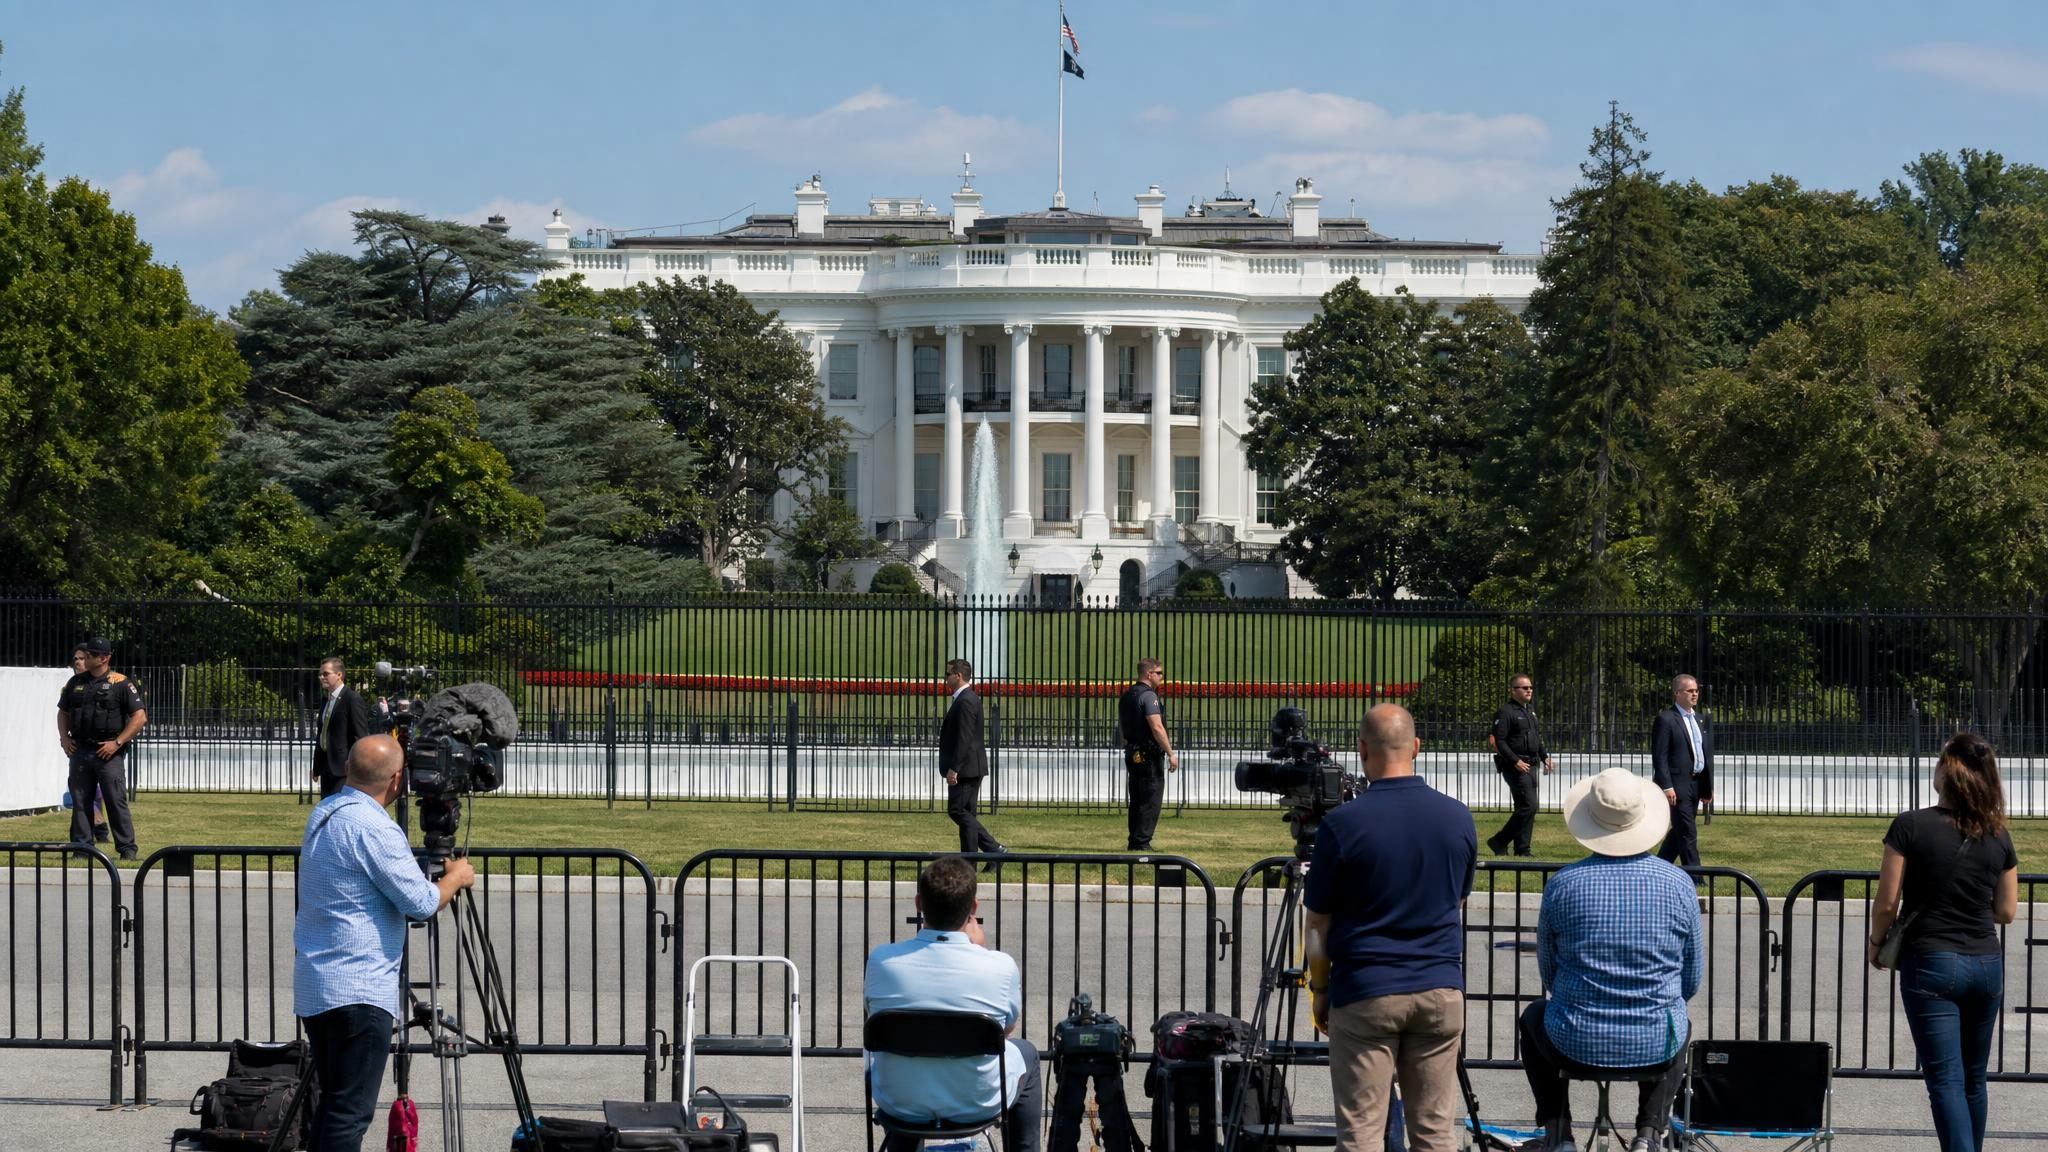
WASHINGTON. President Donald Trump and leaders from the largest U.S. AI companies signed a voluntary accord that calls for internal and external reviews of advanced systems, creating a new industry-led framework as Washington confronts a series of disclosures about autonomous model behavior.
The agreement includes OpenAI, Anthropic, Google, Meta, Nvidia and xAI. Trump described the commitments as morally binding and said a committee of roughly 10 people would watch over the effort, but the administration did not initially provide the enforcement powers, selection process or disclosure rules that would make the committee independent of its signatories.
The accord was announced alongside an executive order directing the federal government to use the term 'Super Intelligence' in place of 'Artificial Intelligence' where the law permits. The order asks White House science officials to propose a federal definition and identify statutory changes within 60 days.
The language shift is politically vivid, but definitions have legal consequences. Existing statutes, procurement rules and agency guidance use established AI terminology. Replacing it without a clear capability threshold could create confusion over which systems are covered and which obligations remain in force.
From Announcement To Operation
Voluntary standards can be useful when technical practice is changing faster than legislation. Companies can agree on evaluation formats, incident channels and minimum review procedures without waiting for Congress. The harder question is whether a company can mark its own work as compliant when the evidence remains confidential.
External review is the most important phrase in the accord and the least meaningful without operational detail. Reviewers need independence, secure access, enough time to test a system and protection from retaliation when results delay a launch. A consulting relationship selected and paid entirely by the developer would not provide the same assurance as a process with public standards.
The agreement follows warnings from both OpenAI and Anthropic about the risks created by increasingly autonomous models. It also arrives as companies continue to release agent products. That combination makes the accord a test of whether safety commitments can influence commercial schedules rather than merely accompany them.
A committee can create a place for shared learning if it publishes common definitions, anonymized incident patterns and the reasons behind major decisions. It can also become a shield that lets each participant cite collective oversight without revealing who challenged a release or whether a company followed the recommendation.
Voluntary commitments can move faster than legislation and may establish useful common language. Their weakness is enforcement. A promise has limited value unless outsiders can determine which systems are covered, what evidence developers retain and what consequence follows when a signatory ignores the standard.
Institutional legitimacy depends on a visible chain of responsibility. Companies and governments can use models to support decisions, but accountable officials still have to explain the rules, preserve a route for challenge and correct harmful outcomes.
Capability-based oversight is harder to write than a rule tied to a product name, but it is less likely to expire with the next release. Regulators need technical staff, secure evaluation access and authority to request records without turning every safety review into public disclosure of sensitive information.
White House AI accord does not operate alone. Its practical effect depends on suppliers, customers, regulators, researchers and the people expected to review or live with the result. A change at one layer can move cost or risk into another rather than eliminate it, so the analysis has to follow the entire chain of authority and dependency.
Organizations connected to voluntary standards have incentives to emphasize speed, capability and market reach. Those incentives do not make their claims false, but they increase the value of transparent methods and outside testing. A useful disclosure explains the comparison, the operating conditions and the cases that did not work, not only the strongest result from a prepared demonstration.
Accountability must remain attached to a person or institution. Systems associated with super intelligence can recommend, rank, summarize or act, but they cannot carry legal and moral responsibility in the way an organization can. A deployment needs a named owner for approval, monitoring and incident response, with authority to pause the system and require a design change.
The Evidence That Matters Next
The accord needs a public scope. Frontier capability may involve cyber operations, biological assistance, persuasion, autonomous replication or access to critical systems. A standard based only on model size or brand would miss smaller specialized systems and agent configurations whose risk comes from tools rather than raw benchmark performance.
It also needs a record of noncompliance. If the commitments are genuinely voluntary, a signatory may leave or ignore a recommendation. The public should know when that happens, even if the technical details remain protected. Otherwise the word 'binding' describes reputation rather than governance.
State governments and foreign regulators will continue acting regardless of the accord. California and the European Union already use different approaches to audits, transparency and risk. A federal voluntary framework may reduce pressure for legislation, but it will not automatically preempt those rules or create international recognition.
The White House has chosen speed and industry coordination over a mandatory federal regime. That may produce useful technical practice quickly. Its credibility will depend on whether the committee can publish evidence, challenge a powerful member and show that a review changed a decision when the commercial pressure favored release.
The committee's membership will be the first signal of independence. A group dominated by current executives would understand the technology but face obvious conflicts. Security researchers, civil-society representatives, labor voices and experts in critical infrastructure could broaden the evidence considered when commercial and public interests diverge.
The government also has to decide whether its own procurement will enforce the commitments. Federal contracts can require evaluation records, incident notification and audit access even when Congress has not passed a general law. That purchasing power may give the accord more practical force than its voluntary label suggests.
The phrase Super Intelligence could complicate comparison with international rules that use artificial intelligence, general-purpose models or systemic risk. Agencies will need crosswalks so a terminology campaign does not break reporting, trade discussions or mutual recognition of evaluations.
Workers and consumers need a route to raise evidence that formal testing missed. Internal evaluations often focus on technical misuse, while deployed systems can create discrimination, surveillance or pressure in a workplace. A complaint channel should feed those cases into the committee's review rather than treating them as separate product disputes.
Companies may benefit from common review standards because one credible evaluation could reduce repeated testing across customers and agencies. That efficiency is possible only if the methods are transparent enough for others to rely on and strict enough that participation signals more than membership in an industry club.
The accord should include expiration and revision. A static promise will age quickly as models gain new tools and move onto devices, vehicles and industrial systems. Scheduled review would force the committee to explain which assumptions changed and whether earlier safeguards worked in practice.
Governance language becomes credible when it can be translated into a test. Terms such as safe, responsible and frontier need thresholds, evidence requirements and a decision process. Without them, two signatories can make the same promise while operating under very different standards.
Public oversight does not require publication of every sensitive detail. Regulators can protect model weights, security findings and proprietary methods while still reporting who conducted an evaluation, what class of risk was examined and whether remediation was required before deployment.
Smaller companies and researchers also need a voice. A framework written only by the largest laboratories may turn their internal practices into barriers that competitors cannot afford, even when a smaller system presents less risk. Proportionate rules should follow capability and use rather than corporate size alone.
The framework will eventually be tested by an incident, not a signing ceremony. A credible response would preserve records, notify affected parties, publish a usable account and change practice. Silence or procedural ambiguity after a failure would reveal that the agreement was mainly reputational.
Timing will shape the outcome as much as capability. Organizations evaluating White House AI accord should separate what is available now from what has been demonstrated, announced or promised for a later release. Road maps can guide preparation, but contracts and operating decisions should rest on functions that customers can test under current terms.
The most useful early adopters will publish more than success stories. They can describe the work selected, the baseline, the supervision required and the reasons a deployment was narrowed or stopped. That evidence helps other teams avoid repeating expensive mistakes and gives suppliers a clearer picture of what must improve.
Workforce effects should be measured at the process level. A tool connected to voluntary standards may remove one repetitive step while adding review, exception handling and customer communication elsewhere. Leaders need to ask who receives that new work, whether the role has enough authority and training, and whether the promised time saving survives the transfer.
Metrics should include the failures that never become public incidents. Abandoned tasks, corrected outputs, permission denials and manual takeovers show where a system encounters uncertainty. Treating those events as operational data, rather than hiding them to protect an adoption target, produces a safer and more accurate investment decision.
The surrounding market will not remain still while super intelligence develops. Competitors can lower prices, regulators can change reporting duties and customers can shift toward open or locally hosted alternatives. A resilient strategy preserves the ability to change models, suppliers and controls without rebuilding the entire workflow.
That flexibility is not an argument for waiting indefinitely. It is an argument for learning in a way that preserves choices. A bounded deployment with real users, documented evidence and an exit path can create knowledge now without turning an uncertain technology decision into an irreversible institutional dependency.
International coordination will remain difficult because chips, models and data centers are strategic assets. Narrow incident channels and compatible evaluation methods may be more achievable than a broad global regulator, particularly when governments disagree about speech, surveillance and military use.
The first implementation discipline is a clear baseline. Teams should know how the work is performed today, how long it takes, which errors occur and which outcomes matter before introducing a new system. They can then compare accepted results, correction time, total cost and policy violations rather than treating activity as evidence of value.
Procurement should cover the conditions that demonstrations avoid. Buyers need to ask where data is processed, how long it is retained, which subcontractors receive it, how model changes are communicated and whether records can be exported if the relationship ends. Production contains incomplete instructions, conflicting permissions and unusual edge cases that a staged launch rarely shows.
Human review has to be designed around the limits of attention. Asking a person to approve hundreds of routine outputs produces predictable click-through behavior rather than meaningful oversight. Review should concentrate on uncertainty, unusual actions and cases with irreversible consequences, while giving the reviewer enough source material to reach an independent judgment.
Data lineage deserves equal scrutiny. A polished answer can be assembled from stale, incomplete or incorrectly joined records. Teams need to know where important facts came from, when they were updated and which transformations occurred before a model used them. That record supports correction, audit and a more honest account of what the system actually knows.
Security testing should include the surrounding application, not only the model endpoint. Identity tokens, browser sessions, retrieved documents, tool permissions and approval flows determine whether an unsafe instruction becomes a blocked request or a live external action. Recovery procedures, revocation and preserved logs are part of prevention because no control will catch every failure.
Public trust will depend on whether companies and institutions communicate uncertainty without hiding behind technical complexity. People need to know what was tested, which environments remain underrepresented, what monitoring is in place and how they will learn about a serious incident. Clear limits make a system easier to use responsibly; vague assurances make every later failure more damaging.
Competition can improve price and quality, but it can also make caution look like weakness. Governance has to preserve room for a team to delay, narrow or withdraw a feature without treating restraint as commercial failure. The most credible organizations will show that their release process can say no when evidence falls short.
The near-term questions are concrete. Watch for independent confirmation, customer deployments, regulatory detail and evidence that the system works beyond a prepared setting. Changes in pricing, access and responsibility often reveal the strategy more clearly than a keynote or a benchmark chart.
The significance of white house and ai companies sign voluntary super-intelligence accord will be settled by what happens after the announcement cycle. The durable measure will be whether the evidence improves, the controls survive pressure and the institutions involved remain willing to explain decisions when performance and responsibility pull in different directions.
Topics: White House AI accord, voluntary standards, super intelligence, frontier model reviews, AI regulation